Introduction
A community studio prepares materials seven days before each workshop. Predicting attendance from post-event scans would look impressive but would be useless at that deadline. You will first establish a simple baseline, then decide which rows and columns a real earlier prediction may use.
You need Python functions, basic terminal input, pandas selection and joins, and introductory regression/train-test concepts. Python and the scientific libraries are prepared. Every table is original synthetic teaching data; the small sample demonstrates a workflow, not a production forecasting guarantee. The 55-minute duration is an author estimate including reading and ordinary corrections.
Measure a Simple Baseline in People
In this step, you will predict two later workshops from an early median and interpret the average absolute error.
Open the WebIDE Tab. In File > Open Folder, open /home/labex/project/workshop-attendance. The Explorer file tree shows the source modules and CSV inputs together. Select a filename to read it; use Edit > Find to find a function name such as summarize. Python indentation groups statements: keep the four spaces inside a function. After an edit, choose File > Save before running it. An unsaved editor buffer does not change what Python reads.
Use the separate Terminal Tab for the commands below; return to WebIDE when asked to edit. The course's ./python launcher selects its prepared scientific environment. Do not use the editor's default Run button or change its interpreter to repair a course command. cd changes only this terminal's working directory; a reopened terminal needs its own cd. Opening either entry never installs or resets the scene.
The Results Tab reads only actual saved files under output/. All files / Refresh reads current files, View opens one artifact, and Download returns its original bytes. Missing files remain missing: Results never runs analysis, fills results or redraws charts. Return to Terminal before commands.
cd /home/labex/project/workshop-attendance
The prepared ./python launcher uses this course's Python environment. The ./ means “the executable in this directory.” Use it instead of a system Python when running the course files. cat displays a text file without editing it.
cat warmup-early.csv
This small warmup has three earlier actual attendance counts: 12, 18 and 24. Their median, the middle sorted value, is 18 people. A baseline predicts 18 for every later event without using any event features.
cat warmup-later.csv
The later actual counts are 20 for L-7 and 27 for L-2. Their absolute errors are abs(20 - 18) = 2 and abs(27 - 18) = 9. Mean absolute error (MAE) is their average: (2 + 9) / 2 = 5.5 people. “Average error of 5.5 people” is meaningful; a unitless “accuracy” would hide what is being measured. This tiny warmup is separate from the full season used next.
First run the supplied median-only function, without editing it. It calculates a real median from warmup-early.csv; it has not yet implemented the later errors or their MAE. The runner's baseline argument selects this stage and saves the returned dictionary in output/baseline.json.
./python run.py baseline
./python show_results.py baseline
The saved object contains only median_attendance: 18.0. This is a useful limited prediction, not a complete error comparison. The step's check must still report NOT COMPLETE, because the required ID-linked errors and MAE are missing. Running successfully and finishing the task are different things.
In WebIDE open baseline.py and find summarize. Read its two arguments: the runner supplies earlier and later pandas tables. Keep the existing median calculation. Return to Terminal before the next command. Before editing a module, use cp to copy its current bytes to a backup. This preserves your current work, unlike starter-*.py, which contains the original incomplete version.
cp baseline.py baseline.py.bak
Return to WebIDE. Inside summarize, replace only the initial return statement with the following body fragment. Keep the existing def line and median calculation. itertuples() visits rows with named fields; the dictionary associates each later workshop ID with its own absolute error. float makes ordinary Python numbers for JSON, a format for named values and objects.
    errors = {
        row.session_id: float(abs(row.actual_attendance - baseline))
        for row in later.itertuples()
    }
    return {
        "median_attendance": baseline,
        "absolute_errors": errors,
        "mae": sum(errors.values()) / len(errors),
    }
Save baseline.py. Return to Terminal and rerun the same stage, then read the actual saved result.
./python run.py baseline
./python show_results.py baseline
The displayed values should include median 18.0, errors 2.0 and 9.0, and MAE 5.5. The reader has read that saved artifact; it never rebuilds a missing result.
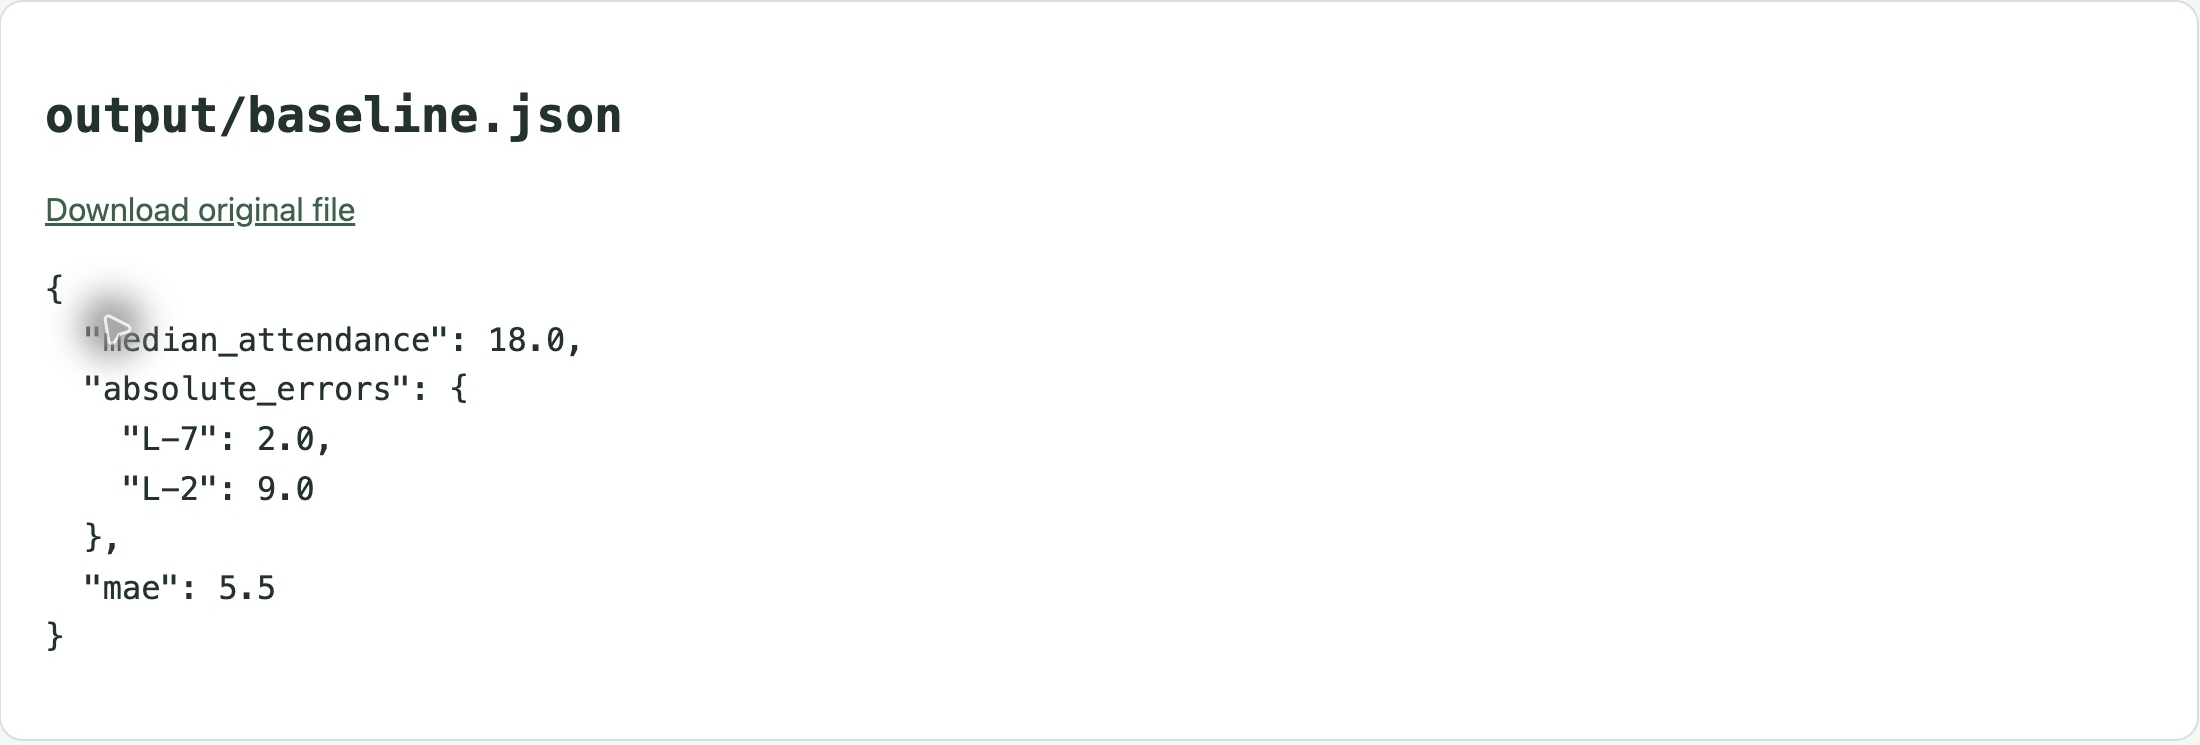
Results shows the saved baseline.json: the early median is 18 people, the two ID-linked errors are 2 and 9, and their MAE is 5.5 people.
You now have a benchmark whose error uses the same units as the planning problem. A later model must be compared on the same evaluation events; beating this warmup value on another sample would not be a fair comparison.
For a Python error, read the traceback's filename and line number, return to that line in WebIDE, fix spelling or indentation, save and rerun. To undo this edit, cp baseline.py.bak baseline.py restores the backup you made before editing. You can then edit the same function again. Do not rerun setup or change input CSVs to repair code.
Separate Training Time from Prediction Time
In this step, you will associate outcomes by workshop ID and reserve later dates for evaluation.
Continue in the Terminal Tab at /home/labex/project/workshop-attendance. Read the season boundary and the three main tables.
cat season.json
cat history.csv
cat labels.csv
cat future.csv
The data dictionary is:
| Field | Meaning and availability | Use |
|---|---|---|
session_id |
Stable workshop identity; file order is arbitrary | Associate rows, never a model feature |
event_date |
Scheduled event day, ISO YYYY-MM-DD |
Decide the time split |
booked_7d |
Booking snapshot saved exactly seven days before the event | Allowed numeric feature |
duration_minutes |
Workshop duration already announced at the seven-day deadline | Allowed numeric feature |
final_bookings |
Final booking total at the event | Unavailable at the prediction deadline |
scanned_entries |
Entry scans collected at the event | Unavailable at the prediction deadline |
actual_attendance |
Outcome known by the end of the event day | Training target or held-out evaluation label |
A blank numeric CSV cell means missing information, not zero bookings. Every allowed feature has at least one observed training value. IDs are unique within each table; labels.csv contains exactly one outcome per historical ID, deliberately in a different order. future.csv has no outcomes or post-event columns. Invalid keys, all-empty training features and rolling model updates are outside this course's input scope.
The model is trained once and frozen on April 1, 2026 at 00:00 UTC, as_of_date. Only events before that date can contribute training labels. In this supplied season the last training event is March 8, so those labels are already available. The holdout starts on April 12, holdout_start; its earliest seven-day prediction deadline is April 5, after the training freeze. There are no supplied historical events in the gap.
These are different clocks: April 1 freezes the fitted model; each later event supplies its own booked_7d snapshot on its own prediction date. The April 12 event's April 5 snapshot is used on April 5, not claimed to be known on April 1. This file-based exercise replays those saved snapshots. The later actual labels are revealed only to measure performance retrospectively. May workshops in future.csv remain unlabeled forecasts.
Read split.py in WebIDE. Its marked unfinished attempt attaches the label array by position, then calls the last two file rows the holdout. Before fixing it, use the existing runner to expose that error:
./python run.py split
./python show_results.py split
These diagnostic files are not an accepted split. Trace W-88 from history.csv to its independent row in labels.csv: its label is 46. A label in the same file position can belong to another event. The check must reject the incorrect identities or period membership even though the command ran.
Return to Terminal to back up this module.
cp split.py split.py.bak
In WebIDE find split_events. Keep the prepared pandas import and function signature. Replace only this function's body, using the complete reference below to identify its indented statements. Do not change the input files or paste a fixed list of workshop IDs.
A one-to-one merge associates labels by session_id. pd.to_datetime parses event dates, pd.Timestamp parses each configured boundary, and boolean masks select the periods. Sorting by date and ID makes the output readable; ID spelling does not choose a period. .copy() makes independent selected tables.
Complete split reference
This is the single complete reference for this function, including its already-prepared import. Read it in the lesson; edit only the function body in your existing file. The next independent lab receives this same completed function.
import pandas as pd


def split_events(history, labels, season):
    events = history.merge(labels, on="session_id", validate="one_to_one")
    dates = pd.to_datetime(events["event_date"])
    train = events.loc[dates < pd.Timestamp(season["as_of_date"])].copy()
    holdout = events.loc[dates >= pd.Timestamp(season["holdout_start"])].copy()
    return (
        train.sort_values(["event_date", "session_id"]),
        holdout.sort_values(["event_date", "session_id"]),
    )
Save split.py, return to Terminal and run the corrected stage.
./python run.py split
The training order should be W-91, W-04, W-77, W-12, W-63, W-02; the holdout IDs are W-88, W-09. These irregular IDs demonstrate why neither alphabetical order nor the last two file rows define the split.
./python show_results.py split
Check W-88: it must retain actual attendance 46 from its matching label, not the label at the same row position. The saved training.csv and holdout.csv still include post-event columns for inspection. The next step will select only the two allowed features; numeric storage does not make a column legitimate for prediction.
If you accidentally close the terminal, reopen the Terminal Tab and repeat the cd above. A “No such file or directory” error usually means the wrong directory or a misspelled filename. Use pwd to display the current path and ls to list its files, then return to this workspace and rerun the intended command. Do not restart the lab to correct an ordinary path mistake.
Learn Missing-Value Means from Training Only
In this step, you will fit one imputer on earlier workshops and reuse it on later snapshots without learning from them.
Continue in the Terminal Tab at /home/labex/project/workshop-attendance. You may edit baseline.py, split.py, prepare.py and your output/ files. Preserve all supplied CSV/JSON inputs, python, run.py, coursekit.py, show_results.py and every starter-*.py. A backup made with cp retains your current module; the starter copies restore only its initial incomplete state and would discard its edits. The main functions must remain reusable when dates, row orders and numeric values change.
Imputation replaces a missing feature with a learned value. SimpleImputer(strategy="mean") learns each column's arithmetic mean. Here booked_7d has training observations 10, 20, 40, 25 and 35: the mean is 26. The six known durations average 80 minutes. Using all periods would let later workshops influence these training choices, even without their outcome labels. Fit after the split, not before it.
FEATURES, supplied by coursekit, is exactly ['booked_7d', 'duration_minutes']. Double brackets select those two columns in that order. fit learns the means; transform reuses them to fill any of the three matrices. statistics_ exposes the learned means in feature order. The returned arrays preserve each input table's row order so the wrapper can retain its IDs.
Open prepare.py in WebIDE and find prepare_features. Its current imputer.fit learns from pd.concat of training, holdout and future rows. This concatenation combines periods before learning the means: later snapshots can influence the earlier training workflow. Read the following transform calls too; they already reuse that fitted imputer.
Return to Terminal for the backup command.
cp prepare.py prepare.py.bak
Return to WebIDE. Change only the imputer.fit(...) line to:
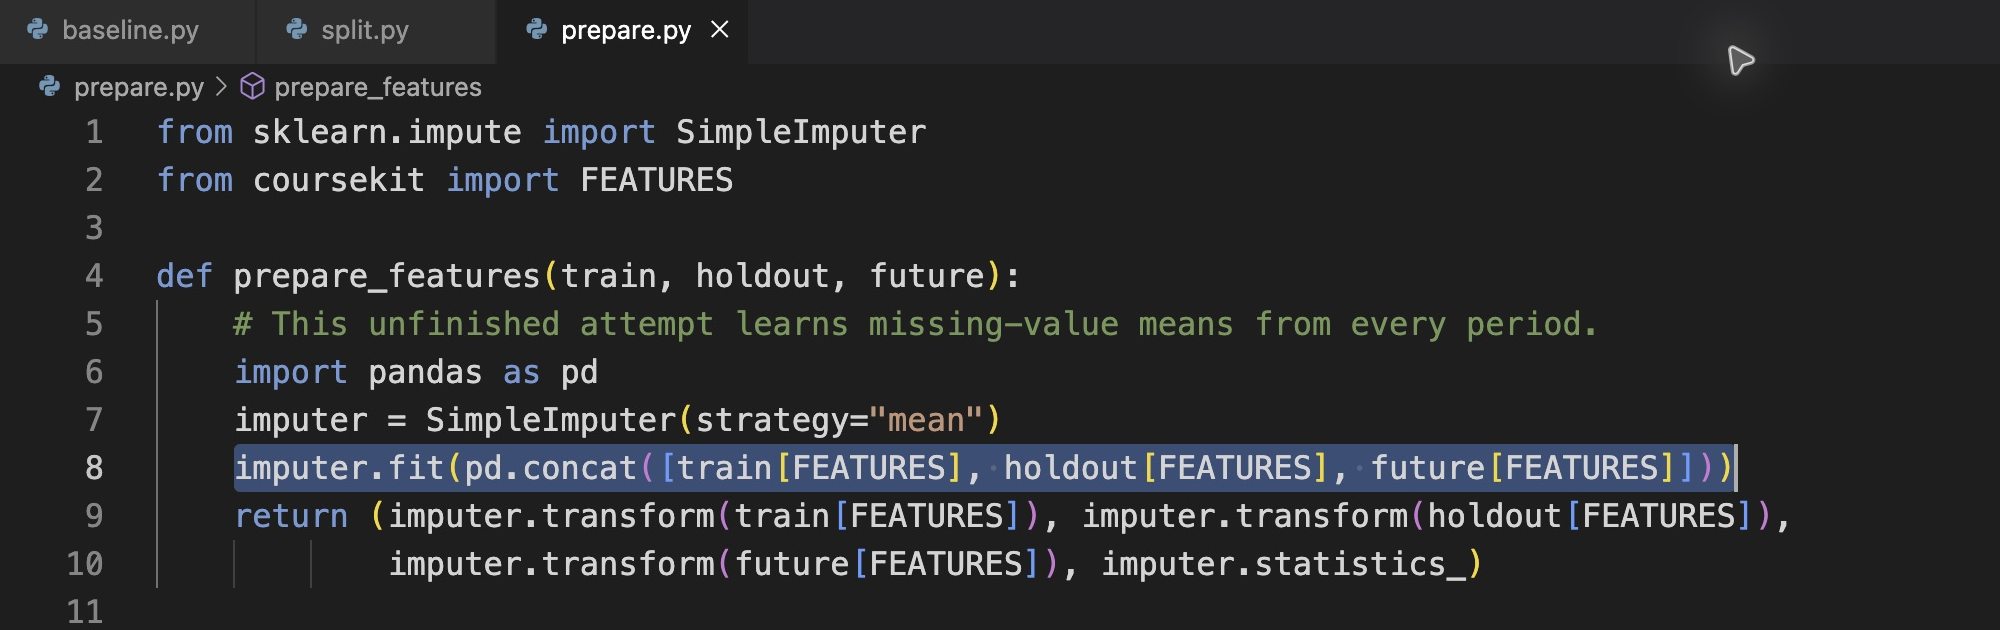
Select only the incorrect fit line in prepare.py. Replace it with the training-only call below, while leaving the three transform calls unchanged.
imputer.fit(train[FEATURES])
Keep the existing return tuple and all three transform calls. The first call fills training data using its own means; the other two reuse those same means without fitting. The existing imputer.statistics_ returns means in feature order. You may remove the now-unused local pandas import, but it does not affect the result. Save the file and return to Terminal.
./python run.py prepare
The learned means should be booked_7d: 26.0 and duration_minutes: 80.0.
./python show_results.py prepare
In holdout-features.csv, W-88 uses 26 bookings and its observed 150 minutes; W-09 retains 90 bookings and uses 80 minutes. In future-features.csv, F-101 uses the same training booking mean. No final bookings, scans, dates, IDs or outcomes enter these numeric matrices. The original blank cells remain unchanged in the source files.
You have prepared a genuine earlier-to-later evaluation boundary. This does not prove the future behaves like the past. The next independent lab will fit a small model and compare its continuous errors with a training-median baseline on the same labeled holdout. Equivalent calculations and different output row orders are accepted when their ID associations and numerical meaning are unchanged; numeric comparisons allow 1e-8 absolute and relative tolerance.
If this module needs recovery, cp prepare.py.bak prepare.py restores its earlier version without changing your completed baseline or split. Reapply the training-only fit, save and rerun prepare. After changing the split itself, rerun split and then prepare so saved downstream files reflect the new identities.
Summary
You created a reusable median baseline, measured MAE in people, joined event outcomes by ID and separated earlier training from later evaluation dates. You selected only information available at the seven-day deadline and fitted missing-value means on training rows alone. The saved tables retain the original identities and preserve the source data for the next stage of analysis.